Groupsites are branded collaboration communities that empower groups of all types and sizes to communicate, collaborate and connect around a shared mission, organization, cause or company.
$99/month
All-inclusive
No per-user fees
Try FREE for 30 days
No credit card required
After free trial ends, 30 days notice prior to cancellation
How was everyone's experience with the CAP WBGQ-B Quality Cross Check?
I remember last time, folks had issue with the sample. This time around, I noticed the nurses having issues with vial 5 and 6 where it was difficult in getting the sample out.
I was working with the nursing unit to run these samples and I kept a close eye on their technique and will say that almost all of them performed it as the instructions from CAP.
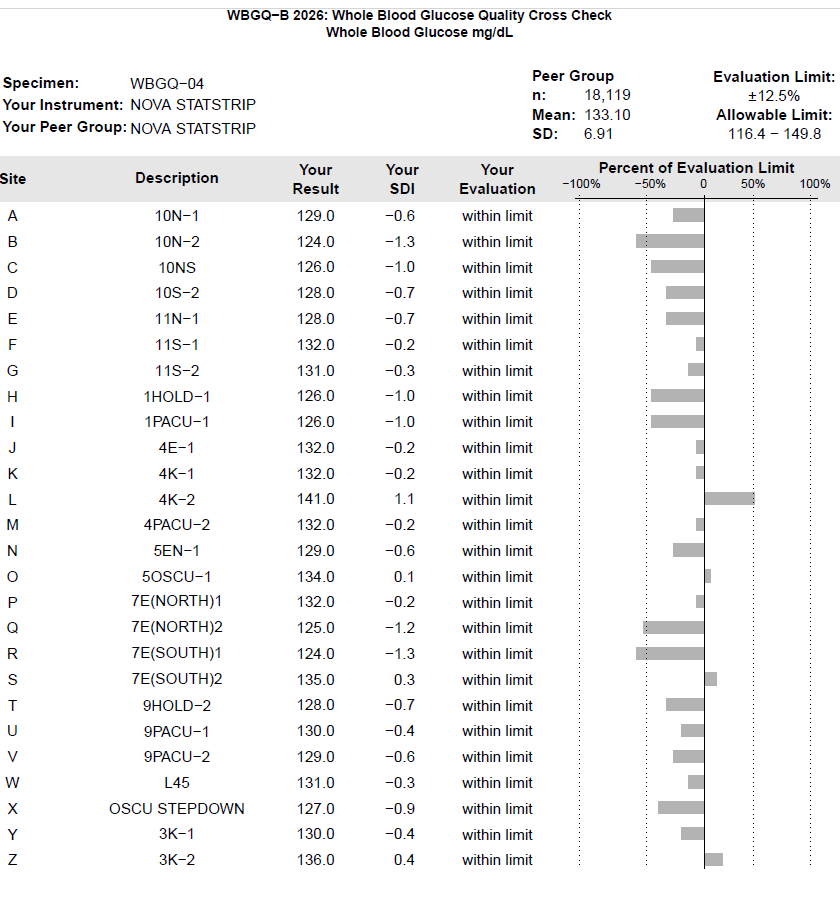
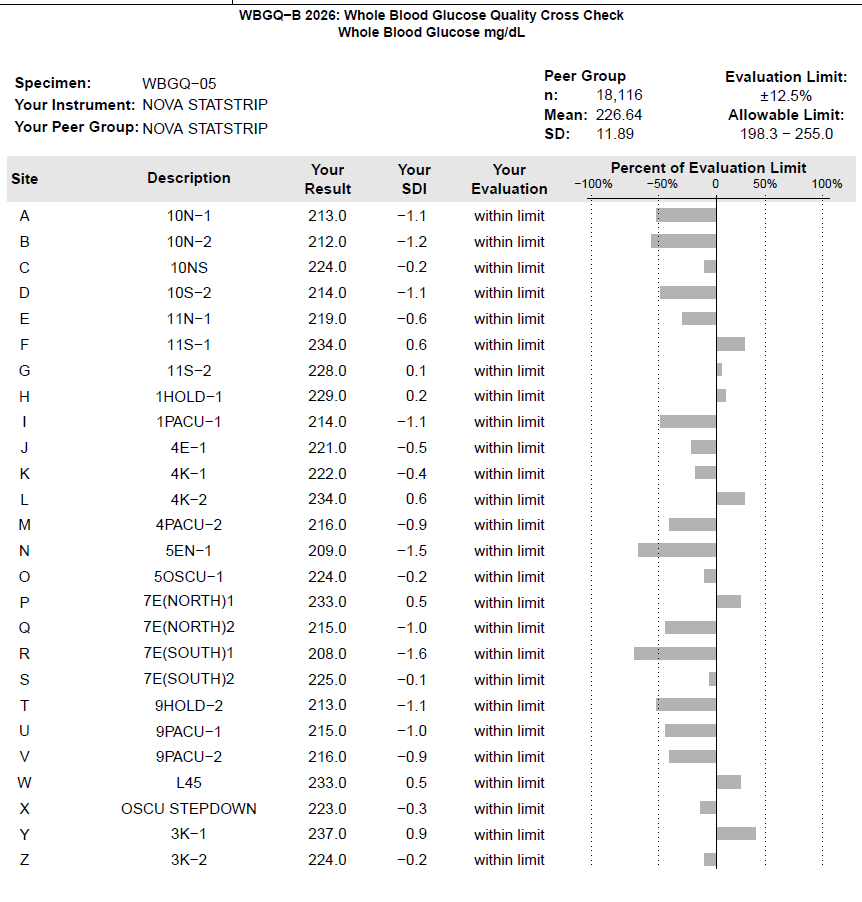
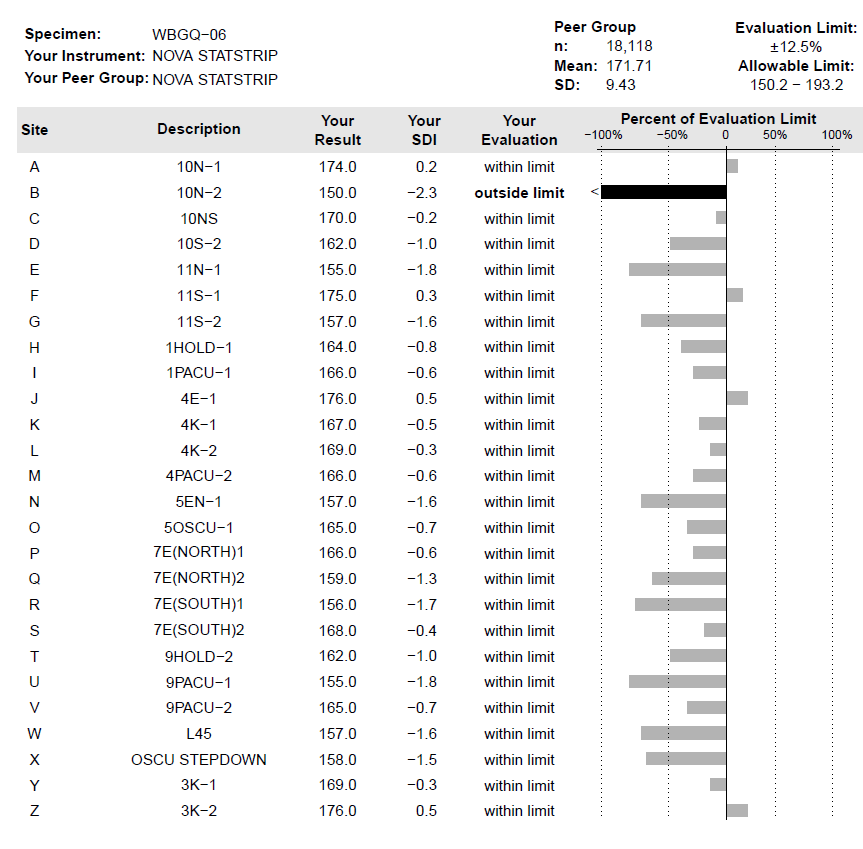
Looking at my results, I do see a negative bias compared to the peer group. The fact that most of my glucometers have a negative bias informs me that it is not device specific. I reran the sample that was out after we received the results from CAP and the value was much closer to the peer average.
I'm trying to figure out the root cause of why my glucometers has a negative bias to the peer group. If the procedure was followed exactly, what reason could it be? Strip Lot to lot variation? Maybe? User Technique? Can't be if the bias is across the board. Not well mixed samples. Nah, I saw them mix. I can't "calibrate" the glucometers and I can't replace all the of them either.
When is bias significant enough for me to act? Should I be concerned about my results?
Our CAP WBGQ surveys have always had a positive bias even with the previous survey material - Do you participate in the "Within Laboratory Difference Report"? Our lab comparison criteria is 15%.
As long as all meters fall within the peer group & the 15% lab comparison criteria, we call it a win. Only perform repeat testing and calibrations if outside either of these parameters.
Ever since CAP switched to this survey material, I've found issues with the material coming out of the bottles. I've even noticed small dark ""granules" in the solution. Think this causes a dam in the tip of the bottle. If you gently mix it and dispel some of the solution the tip flows better.
Hi Jo, I agree with Mimi, it you are within your selected criteria (we also use 15%) don't worry about it. Different strips lots can impact the results. On our last WBGQ survey we tested 33 devices and had three outside the peer mean. Our remediation was to run linearity on each of them and QC and left it do. The last few sample materials were a mess, as Mimi mentioned, the sample would get clogged in the tip or we found that it shot out in a large drop creating a mess and improper sampling. We trust our lab correlation more than this survey but it doesn't serve the purpose of device-to-device cross check. Best, Colette
Jo, I would agree with you that this is most likely a LOT-to-Lot variation. We use the StatStrips, in this survey WBGQ-B 2026 we averaged on sample #4: -2.5%, #5: 0.5%, #6: 4.5% bias. Our facility has a policy to address any survey result that is >2SDI from the peer mean. It does not split out the POC analyzers, the vast majority of which can NOT be re-calibrated. I've gone "around and around" with the Quality Manager regarding this. This WGBQ survey fortunately has a wider allowable limit due the number of labs and different platforms using this survey. I've got a couple other surveys that have tests that if we don't hit the exact peer mean we are >2SDI. When we first went live with the StatStrip we obtained a LOT that was only 1 week old from the manufacturer. We were likely the only system using the specific LOT when we reported the results which had a significant bias. My Quality manager wanted me to correct the bias; I never got an answer on how they proposed I could do that.
Mimi Casavant
I agree with Mimi, it you are within your selected criteria (we also use 15%) don't worry about it. Different strips lots can impact the results.
On our last WBGQ survey we tested 33 devices and had three outside the peer mean. Our remediation was to run linearity on each of them and QC and left it do.
The last few sample materials were a mess, as Mimi mentioned, the sample would get clogged in the tip or we found that it shot out in a large drop creating a mess and improper sampling.
We trust our lab correlation more than this survey but it doesn't serve the purpose of device-to-device cross check.
Best,
Colette
It may be endemic to the brand..
I would agree with you that this is most likely a LOT-to-Lot variation. We use the StatStrips, in this survey WBGQ-B 2026 we averaged on sample #4: -2.5%, #5: 0.5%, #6: 4.5% bias.
Our facility has a policy to address any survey result that is >2SDI from the peer mean. It does not split out the POC analyzers, the vast majority of which can NOT be re-calibrated. I've gone "around and around" with the Quality Manager regarding this. This WGBQ survey fortunately has a wider allowable limit due the number of labs and different platforms using this survey. I've got a couple other surveys that have tests that if we don't hit the exact peer mean we are >2SDI.
When we first went live with the StatStrip we obtained a LOT that was only 1 week old from the manufacturer. We were likely the only system using the specific LOT when we reported the results which had a significant bias. My Quality manager wanted me to correct the bias; I never got an answer on how they proposed I could do that.